Research
🔭 Research Overview
My research agenda is to build causality-aware graph data management and reliable graph data infrastructure for AI. I study how graph structure, causal signals, and scalable data systems can make AI applications more trustworthy, explainable, and efficient. The four directions below line up with my publications and ongoing projects.
Q1 Causally Explainable Graph Data. Causal property graph data models, CDAG construction, and scalable intervention analysis over large graph data.
Q2 Reliable Graph Infrastructure for AI. Cost-efficient graph-based RAG, structured retrieval, graph memory, and agentic retrieval for knowledge-intensive tasks.
Q3 Dense Structure at Massive Scale. Scalable algorithms for densest subgraph discovery, community search, clique and biclique counting, and graph similarity.
Q4 Large Models for Data Systems. LLM-powered and pretrained methods for data systems: latency prediction, cardinality estimation, and automated DBMS testing.
🧩 Research Topics
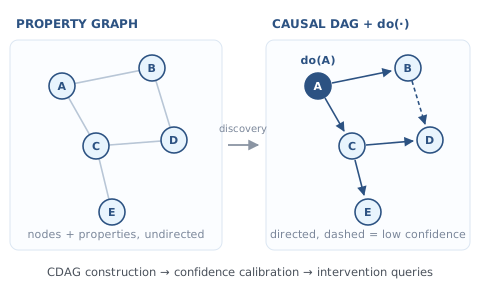
Causal Property Graphs and Scalable Causal Analysis
I study causal data management over property graphs, unifying graph structure priors with statistical learning for robust causal graph construction and fast inference. This is the direction I started at CNRS LIRIS and it does not have published results yet.
- CDAG construction from temporal constraints, graph topology, and domain priors.
- Hybrid structure learning with conditional-independence tests and score-based optimization.
- Large-scale causal analysis via subgraph pruning, parallel discovery, and incremental updates.
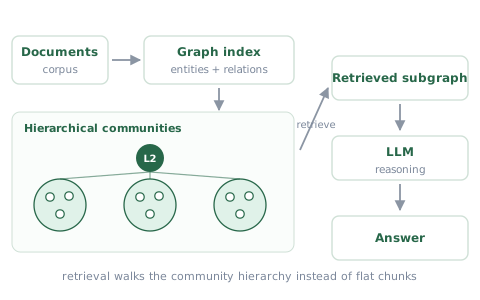
Graph-based LLM Systems
I study graph-based retrieval, memory, and reasoning for large language model systems, with a focus on efficient RAG frameworks, indexing, and tuning.
- In-depth analysis of graph-based RAG in a unified framework VLDB'25
- Automatic RAG tuning via hierarchical memory-guided search SIGMOD'26
- Index and retrieval methods AAAI'26ICDE'26VLDB-W'25
- Evolving and long documents arXiv EraRAG, BookRAG
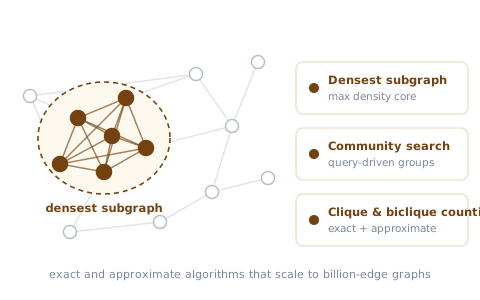
Graph Mining and Graph Algorithms
I design scalable graph mining algorithms for densest subgraph discovery, community search, clique and biclique counting, and graph similarity tasks.
- Densest subgraph discovery SIGMOD'24VLDB'25 ×2SIGMOD'26 ×2KDD'26
- Community search VLDB'23SIGIR'25VLDB'26SIGMOD'26
- Counting and similarity VLDB'24 ×2VLDB'25VLDB'26 ×2
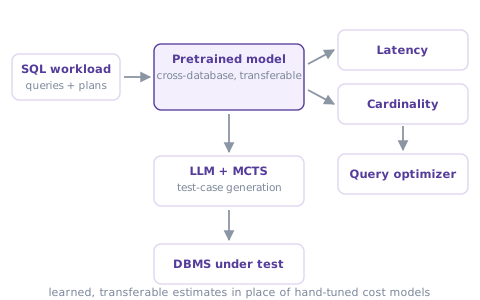
Large (Language) Models for Data
I build LLM-powered and pretrained methods for data systems, covering latency prediction, cardinality estimation, DBMS testing, and real-time data warehouse engines.
- Pretrained models for database optimization VLDB'25VLDBJ'26
- LLM-based test-case generation for DBMS ICSE'26 · Best Paper
- Real-time data warehouse engines VLDB'25 with Alibaba Cloud
💻 Open-source Projects
- 🔮 DIGIMON / GraphRAG — the first unified graph-based RAG prototype system for structured retrieval and reasoning over complex data.
- ⏳ EraRAG — the first graph-based RAG system to handle evolving documents.
- 📚 BookRAG — a hierarchical structure-aware index for retrieval-augmented generation over complex documents.
- 🌍 MicroWorld — turns multi-modal event material into structured graphs, agent populations, and inspectable social simulations.